ARGELLAN / ONTAREN
ONTAREN
Turn source material into knowledge people can use.
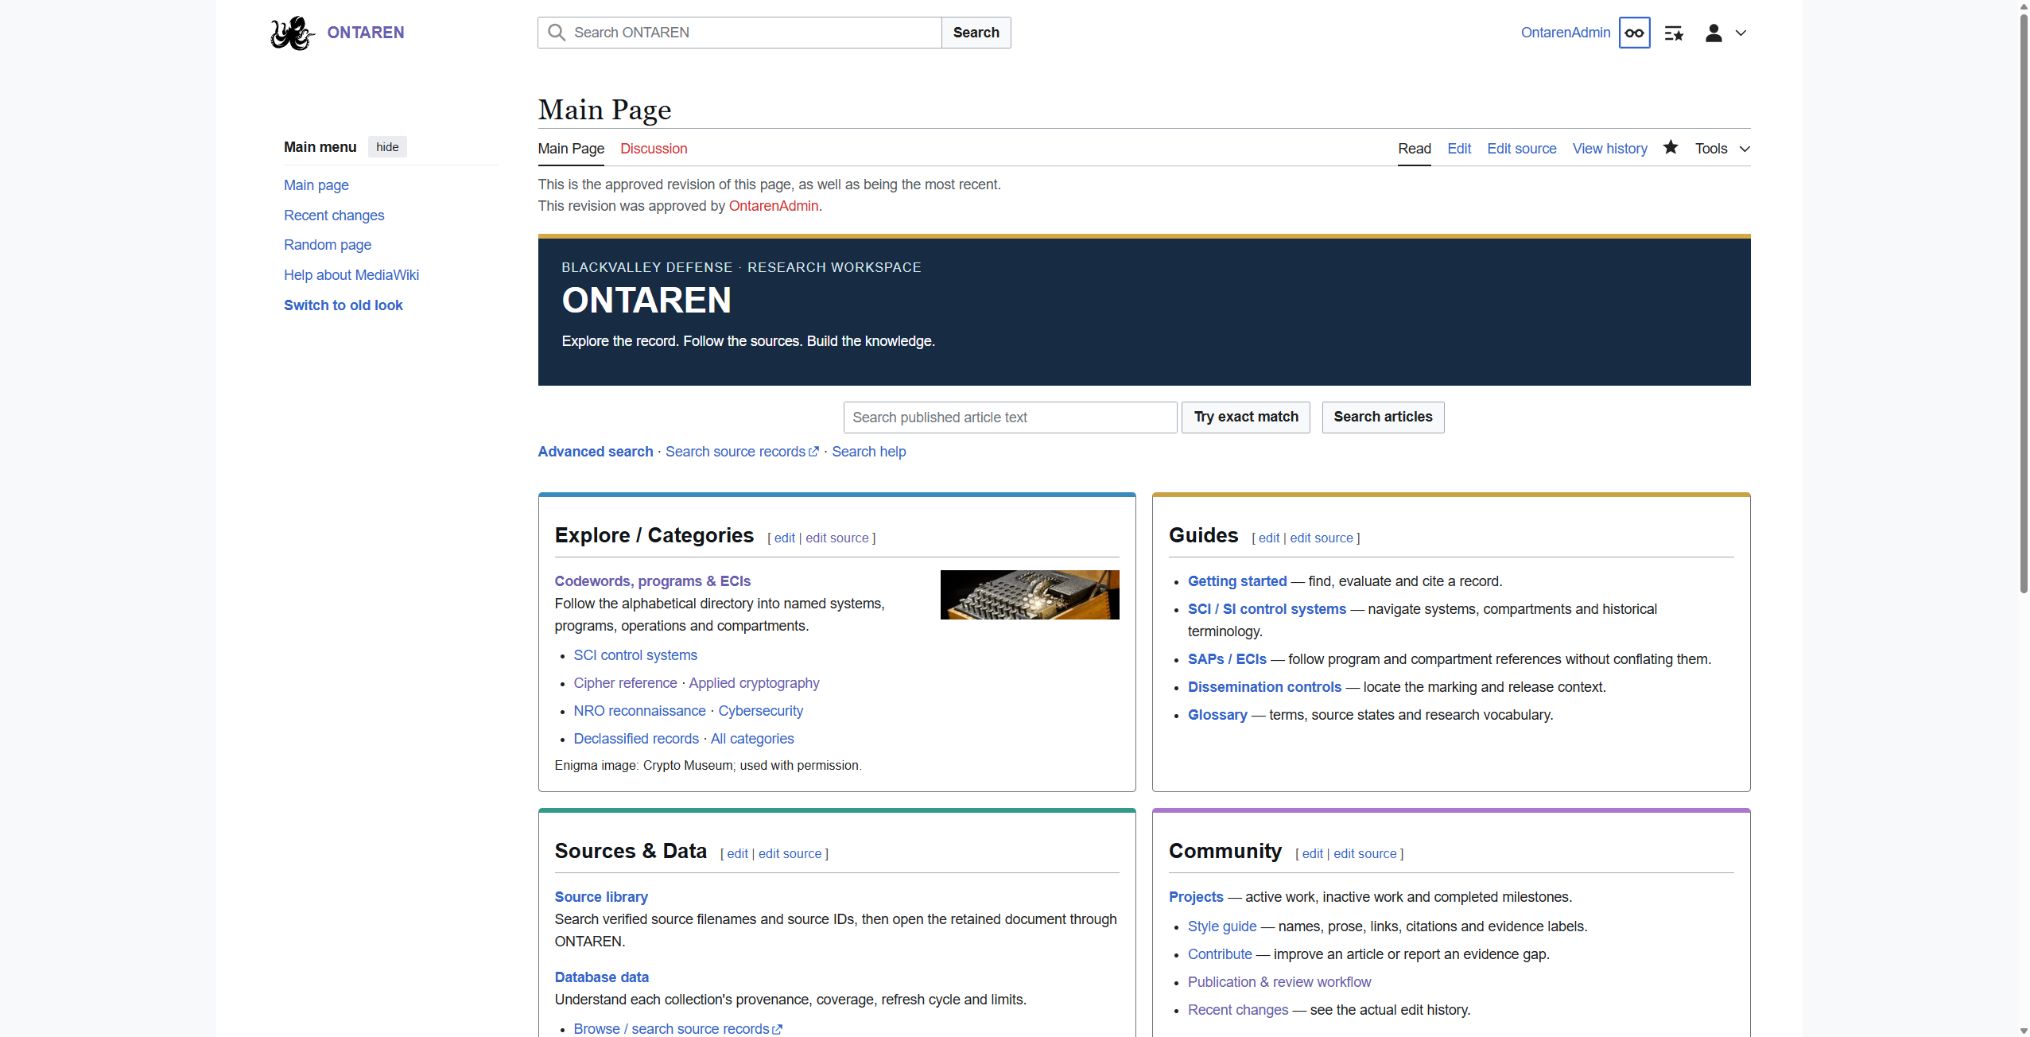
ONTAREN is a private intelligence encyclopedia built around sourced articles, local reference material and controlled publication. It gives research teams a shared reading and authoring environment while keeping articles connected to their evidence, media and revision history.
For research teams building a durable knowledge base
ONTAREN serves analysts, researchers and editors who need to turn collections of reports and references into navigable knowledge. Its MediaWiki foundation supports collaborative articles and native revisions; structured Source pages preserve the supporting record alongside the narrative.
The publication workflow separates discovery, drafting, review and authorized writing. An imported page, an ordinarily visible page and an approved revision are distinct editorial states. That distinction helps a reader understand which version has passed the relevant review.
From source package to a readable article
Define the source package
Identify the permitted source material, intended article subjects and supporting media. A manifest records the evidence boundary and source identities.
Draft with source context
Prepare article text, Source pages and local links. Review citations and media context so an illustration does not become evidence for an unsupported claim.
Authorize publication
Bind the target, exact payload, rights and review evidence. Create-only or base-revision conditions protect existing pages from an unexpected overwrite.
Read back and inspect
Check the stored revision and media against the expected content, then inspect the reader page for links, image loading and layout. Uncertain writes are reconciled before retry.
Knowledge and publication capabilities
| Collaborative articles | MediaWiki authoring, native revisions and a custom reading interface. |
|---|---|
| Structured Source records | Identifiers, creators, dates and reference fields support traceable source context. |
| Local media collections | Images and documents remain connected to source and rights records. |
| Editorial revision selection | ApprovedRevs separates selected editorial revisions from ordinary publication. |
| Search | Article and source retrieval with full-text, OCR, fuzzy-query and local semantic-search components; coverage depends on indexed material. |
| Controlled publishing | Role-scoped writes, publication envelopes and create-only or base-revision checks. |
| Recoverable queue operations | A single-writer broker, idempotent requests, leases and uncertainty records govern the publishing pipeline. |
Inputs and outputs
Inputs include permitted reports, source captures, article drafts and media with recorded rights. ONTAREN can organize a bounded publication package into articles, Source pages, categories and media collections.
The output is a readable, searchable knowledge collection with native revision history and publication readback evidence. The source archive, article text and search index serve different roles: a successful publication does not establish that every source body has been indexed or every revision approved.
Technical profile and deployment discussion
| Reader and authoring application | MediaWiki with PHP and MariaDB; a native ONTAREN skin uses Mustache and ResourceLoader. |
|---|---|
| Editorial and structured content | ApprovedRevs, Cargo and Page Forms for editorial and structured content workflows. |
| Search stack | CirrusSearch, Elastica and OpenSearch, with a separate local semantic service. |
| Semantic processing | Local ONNX embedding model; the inspected design does not send document contents to an external embedding endpoint. |
| Publishing services | Python/SQLite queue broker and constrained workload roles; Docker Compose and existing system scheduling for the publishing runtime. |
| Access model | Private wiki within a shared read domain. Editorial approval is distinct from per-record confidentiality enforcement. |
| Integration boundary | KRIL remains a separate document-custody system. The proposed bridge is separate integration work. |
| Sizing discussion | Plan source volume, OCR backlog, indexing and publishing workloads separately from interactive reader demand. |
Questions about ONTAREN
How is ONTAREN different from a document repository?
ONTAREN organizes knowledge into articles, source records and navigation. KRIL addresses authoritative document custody and records decisions. They have complementary responsibilities, but their proposed bridge is a separate integration.
Can search cover PDFs and OCR text?
The search implementation includes PDF/OCR text and local semantic components. Actual results depend on the indexed sources and successful processing; complete corpus coverage is not assumed.
Does publishing approve an article?
Publication creates or updates a native revision. Editorial approval selects a revision through the configured review process. These are separate states.
Can it enforce different confidentiality rules for every article?
The MediaWiki arrangement is intended for a shared read domain. Requirements for record-level confidentiality need a separate architecture and access-control assessment.
What belongs in an initial product discussion?
Describe the collection, its source and media rights, the reader population, editorial roles and search requirements. These define a useful first publication and retrieval workflow.
Build a knowledge collection with traceable sources.
Tell us what you need to accomplish, the environment you operate and the constraints that matter.
Discuss ONTARENOpens your email application. No message is submitted by this website.